Both say they’re great with AI.
Does it show in real work?
AI Literacy Assessment
Watch people delegate to AI, check its work, and finish the job. Get each person’s strengths and gaps, plus AI skill levels by team and role.
Vague ask → No review
Plan → Ask → Review
Fictional results for two candidates on the same task. Levels match the examples below.
Sample run · 6 scenes
Both say they’re great with AI.
Does it show in real work?
Reports
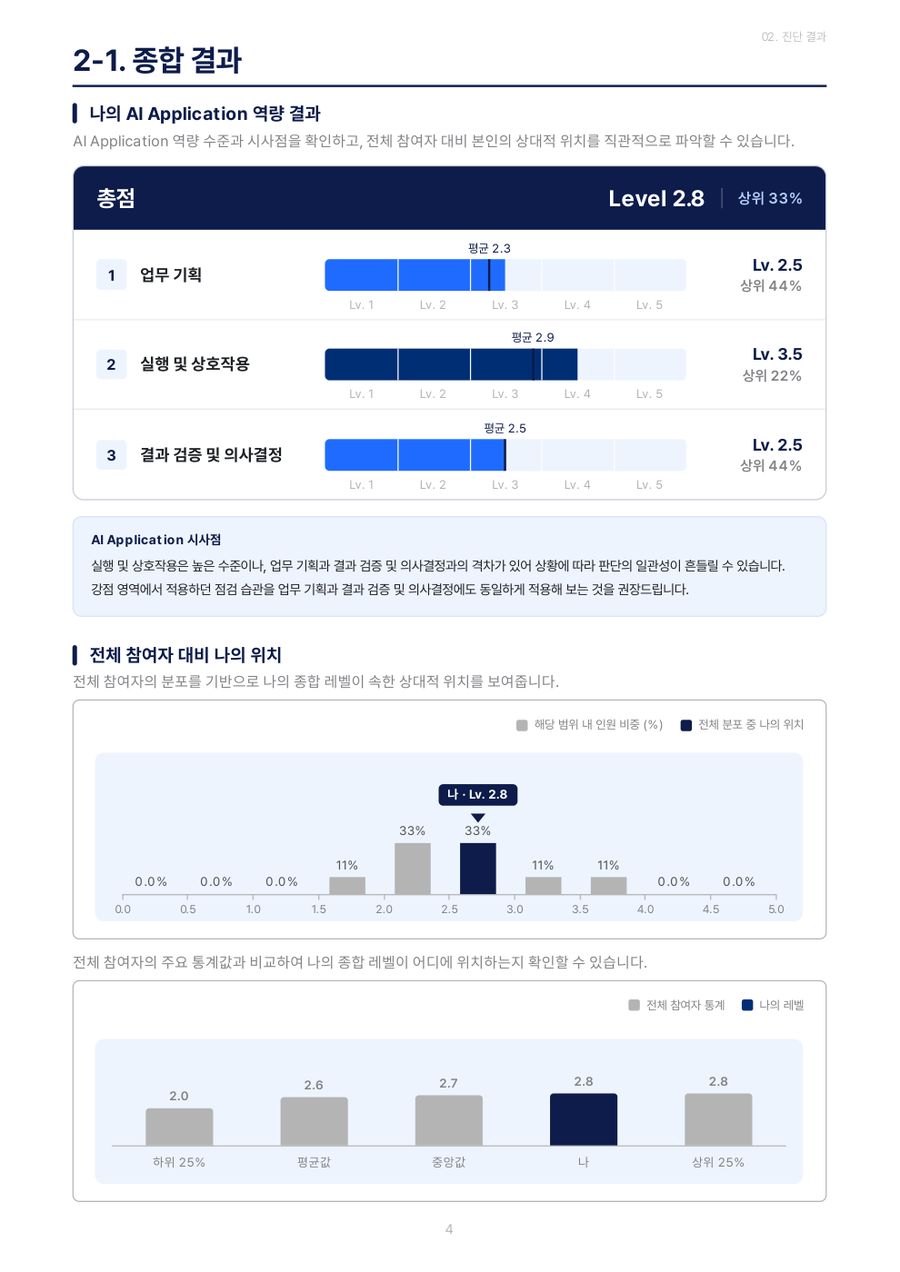
Individual report · Everyone
Levels with evidence, peer standing, how they used AI, and strengths, gaps, and next steps. Concise for hiring; detailed, with feedback, for development.
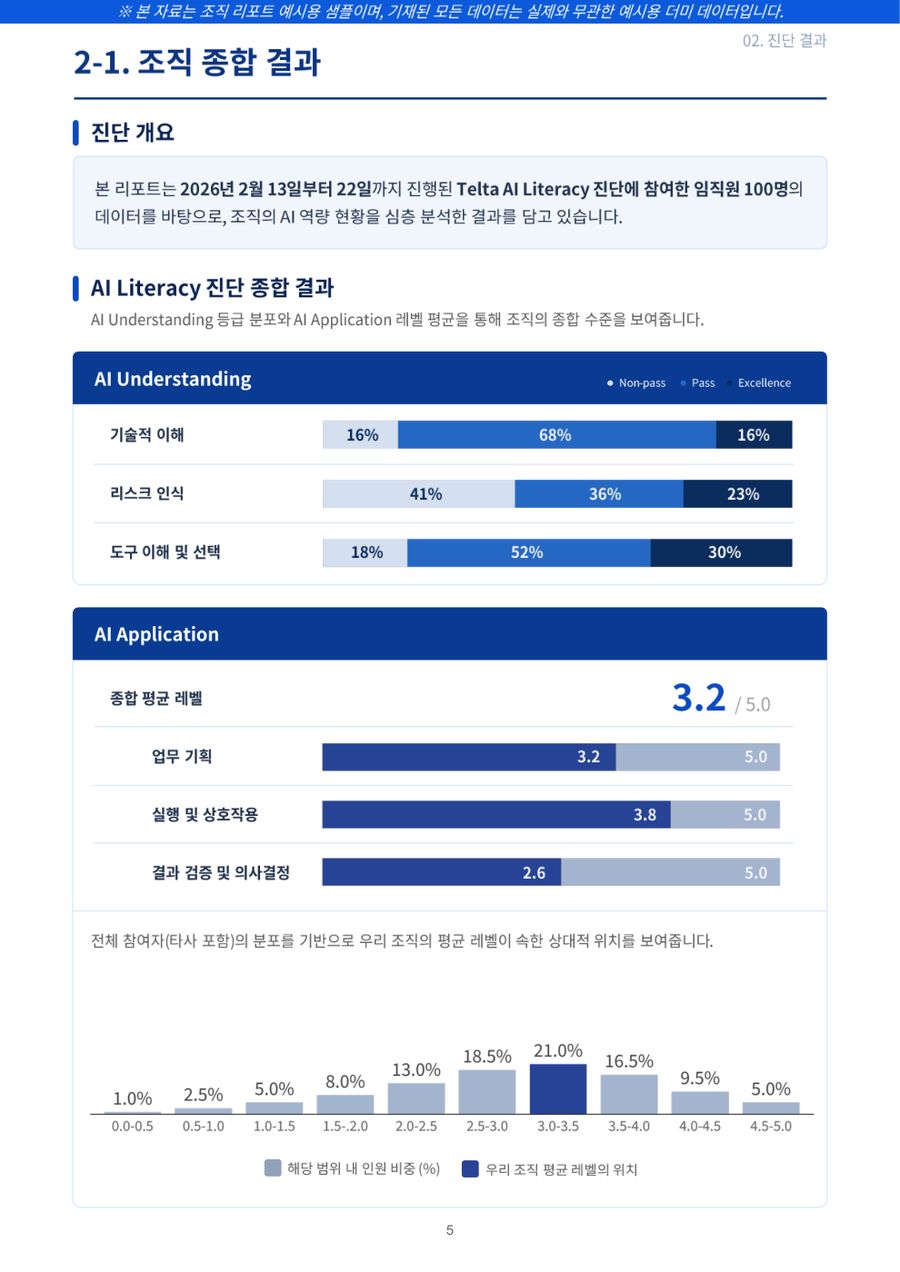
Org report · For comparisons
Compare level spread (Full adds AI understanding grades), team and role gaps, and AI usage. Reassess with the same version to track change.
Sample report data is fictional.
Why it matters
What you track today
What an assessment adds
Test the AI skills on a résumé with a real task.
Compare AI levels, strengths, and gaps across teams and roles.
See how people handle customer and internal data.
How we measure
Knowing the answer isn’t the same as doing the work. A real task shows how people check and fix AI output.
| What you need | Quiz | Self-rating | Real task |
|---|---|---|---|
| How people use AI at work | |||
| Handling sensitive data | |||
| Free of self-report bias | |||
| AI knowledge | What they know | What they think they know | What they apply |
| Delegating to AI | Limited | Self-reported only | Shown in their prompts |
| Checking AI answers | Limited | Self-reported only | Shown in their edits |
| Evidence | Correct answers | Self-scores | Chat log + final answers |
YesLimited
Quizzes test AI knowledge; self-ratings show self-perception. Telta’s tasks capture how people prompt, review, and revise, plus what they deliver.
How it works
Every prompt counts, not just the final answer. We analyze the AI chat and the deliverable together.
Task 1
Decide what AI handles and what you check.
Task 2
Set sources and constraints, then review and refine.
Task 3
Finalize answers and pre-share checks.
Demo · Click a step to jump to it.Tap a step to jump to it.
Sample results
Candidate A · “Great with AI”
Lv1.5
PlanningLv1.5
Execution & InteractionLv1.5
Review & DecisionsLv1.5
Pasted raw customer data and used the AI’s cause unchecked.
Candidate B · “Great with AI”
Lv3.8
PlanningLv4.0
Execution & InteractionLv4.0
Review & DecisionsLv3.5
Removed customer data and flagged the unsupported cause.
Fictional example · The two candidates from the video above.
Turn 300 customer inquiries into a weekly meeting brief.
A kept the unsupported cause. B caught it and had it marked [Needs verification].
Results inform. Hiring and HR managers decide.
Evidence
Candidate B · Request 2
“‘Warehouse relocation’ isn’t in the materials. Mark the cause [Needs verification] and quote the messages verbatim.”
Competency
Caught a cause not in the materials and asked for a fix.
Level
Lv4
Candidate B · Task 1 answer
“Strip customer names and phone numbers before sharing messages with the AI”
Competency
Decided up front what the AI gets to see.
Formal name · Setting human–AI task boundaries
Level
Lv5
Fictional example. Levels come from all answers and the full chat, scored against each competency’s criteria; only key evidence is shown. See all criteria
6
Telta AI scores the chat and final answers against each one.
Individual report
Levels, evidence, strengths, gaps, and next steps.
Using reports
HR and leaders use the evidence to plan interview follow-ups and spot skills to build.
Full framework · 6 areas · 14 competencies
Checks whether people understand how AI works, where it falls short, and what risks to watch for. It also covers risks such as security, copyright, and personal data, and choosing tools that fit the company’s AI policy.
Assessed with Full’s 16 multiple-choice questions, with a grade for each competency area.
Checks whether people hand work to AI with a clear purpose, review its answers, and complete the deliverable.
Competency, area, and overall levels (Lv1–Lv5) based on the AI chat history and final answers.
How we built it
What it’s built on
10 organizations
Public AI skills research from OpenAI, Anthropic, Stanford, the AI Alliance, and others
30 companies
Job data from 30 AI transformation leaders recognized by Fortune
14 competencies
8 for AI understanding and risk, 6 for AI application
HR experts reviewed the resulting framework.
Sales, marketing, HR, and more, measured on one scale.
Telta placed first overall in TalentCLEF 2026 (HCM AI, Tasks A and B).
~25 min
Light · AI tasks
~60 min
Full · Quiz + AI tasks
Lv1~Lv5
Levels for each competency
10,000+
Teams of 10 to entire companies
Versions
Light focuses on AI use. Full adds AI knowledge. Compare below.
One work scenario in three steps, covering 6 AI application competencies.
Benefits
16 quiz questions plus 3 AI tasks, covering all 14 competencies.
Benefits
Side by side
| Light~25 min | Full~60 min | |
|---|---|---|
| Scope | AI application skills 3 areas · 6 competencies | AI understanding and risk + AI application 6 areas · 14 competencies |
| Format | One work scenario in three steps Plan → Chat with AI → Deliver and check | Part 1: 16 quiz questions Part 2: 3 AI tasks |
| Timing | ~25 min · No pausing · Self-paced across steps | ~60 min · No pausing |
| AI use | Built-in AI chat throughout | Built-in AI chat in Part 2 |
| Scoring | AI tasks: scored from the chat log and final answers. Full’s AI understanding: scored from the quiz. | |
| Results | Levels by competency, area, and overall (Lv1–Lv5) | AI understanding: grade by area AI application: Lv1–Lv5 levels |
Tasks and criteria differ by version, so compare results within one version.
Use cases
Hiring
Light · ~25 min
Review how they worked and plan interview follow-ups.
Development
Full · ~60 min
Share detailed feedback, then reassess to measure change.
Organization
Org report
Compare levels and competencies to see where to focus.
Every participant gets a report. We can also build custom versions for your roles or industry.
Taking it
How to take it
Open the link and start. Light takes about 25 minutes, Full about 60. In Light, participants pace themselves across steps. Neither can be paused once started.
The screen
Task brief on the left, AI chat on the right. Participants choose their AI model.
Support
We plan goals, participants, and timing with you, for teams of 10 to companies of 10,000+. Everyone gets an individual report.
Custom versions
We co-design frameworks and tasks for your roles or industry.

